Latent AI
6 minutes
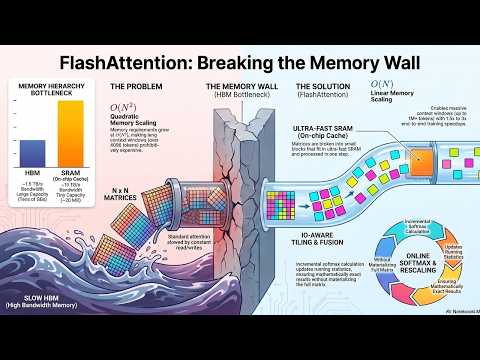
the textbook implementation writes an N-by-N matrix to HBM, and that write — not the arithmetic — is what makes long context expensive
Why this Concept is marked deprecated
Superseded by FlashAttention: tiled online softmax computes identical attention without writing the N-by-N matrix to HBM, removing the real long-context bottleneck.