Hedu AI by Batool Haider
15 minutes
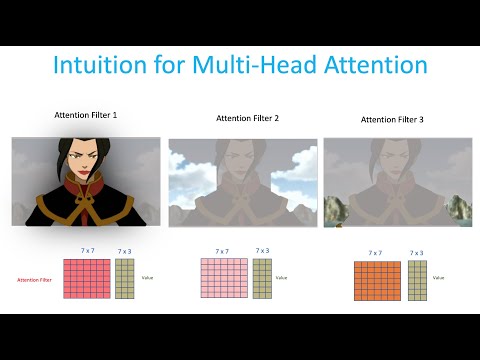
Splitting attention into parallel heads over learned subspaces so different heads capture different relations; concatenation and output projection.
Why this Concept is marked deprecated
Superseded at inference by grouped-query attention: one KV head per query head makes the KV cache the binding memory cost, and grouping recovers most quality for a fraction of it.