Under The Hood
22 minutes
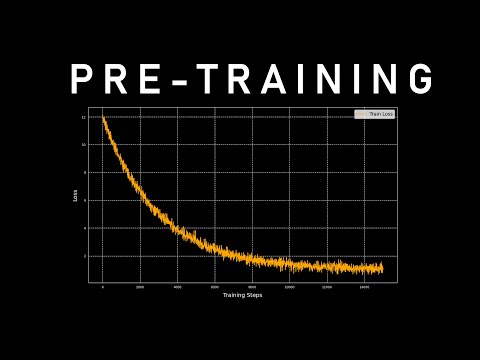
The self-supervised, next-token pretraining of large language models on massive text corpora, including tokenization, the composition and weighting of data mixtures, and budgeting the compute and number of tokens used during the main pretraining run.